Posts

A Comparison of Distributed Machine Learning Platforms

Image
This paper surveys the design approaches used in distributed machine learning (ML) platforms and proposes future research directions. This is joint work with my students Kuo Zhang and Salem Alqahtani. We wrote this paper in Fall 2016, and I will be going to ICCCN'17 (Vancouver) to present this paper. ML, and in particular Deep Learning (DL) , has achieved transformative success in speech recognition, image recognition, and natural language processing, and recommendation/search engines recently. These technologies have very promising applications in self-driving cars, digital health systems, CRM, advertising, internet of things, etc. Of course, the money leads/drives the technological progress at an accelerated rate, and we have seen many ML platforms built recently. Due to the huge dataset and model sizes involved in training, the ML platforms are often distributed ML platforms and employ 10s and 100s of workers in parallel to train the models. It is estimated that an overwhel...
Paper summary: Zorua: A holistic approach to resource virtualization in GPU

Image
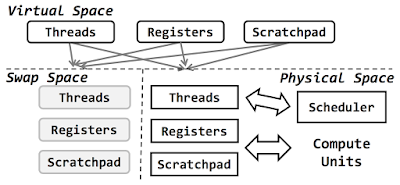
This paper recently appeared in MICRO'16 and addresses the problem of ease of managing GPU as a computational resource. GPU computing today struggles with the following problems: Programming ease: The programmer needs to statically allocate GPU resources (registers, scratchpad, threads) to threads and this is hard and non-optimal as tuning is hard.   Portability: An optimized specification on one GPU may be suboptimal (losing upto 70% performance) on another GPU. Performance: Since the programmer allocates resources statically and fixed manner, the performance suffer and dynamic underutilization occur when the program resource utilization vary through execution. To address the above problems, Zorua (named after the shapeshifting illusionist Pokemon) virtualizes the GPU resources (threads, registers, and scratchpad). Zorua gives the illusion of more GPU resources than physically available, and dynamically manages these resources behind the scenes to co-host multiple applic...

Paper Summary: Two decades of recommender systems at Amazon.com

Image
This is a short article that appeared as a retrospective piece for the 2003 "Item-to-Item Collaborative filtering" paper as it was awarded a test-of-time award. This article is by Brent Smith and Greg Linden.  I am not a machine-learning/data-mining guy, so initially I was worried I wouldn't understand or enjoy the article. But this was a very fun article to read, so I am writing a summary. The item-based collaborative filtering is an elegant algorithm that changed the landscape of collaborative filtering which was user-based till then. User-based means "first search across other users to find people with similar interests (such as similar purchase patterns), then look at what items those similar users found that you haven't found yet". Item-based is based on the idea that "people who buy one item are unusually likely to buy the other." So, for every item i1, we want every item i2 that was purchased with unusually high frequency by people who b...

Paper Summary: DeepXplore, Automated Whitebox Testing of Deep Learning Systems

Image
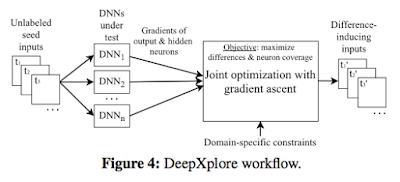
This paper was put on arxiv on May 2017, and is authored by Kexin Pei, Yinzhi Cao, Junfeng Yang, Suman Jana at Columbia and Lehigh Universities. The paper proposes a framework to automatically generate inputs that trigger/cover different parts of a Deep Neural Network (DNN) for inference and identify incorrect behaviors. It is easy to see the motivation for high-coverage testing of DNNs. We use DNN inference for safety-critical tasks such as self-driving cars; A DNN gives us results, but we don't know how it works, and how much it works. DNN inference is opaque and we don't have any guarantee that it will not mess up spectacularly in a slightly different input then the ones it succeeded. There are too many corner cases to consider for input based testing, and rote testing will not be able to cover all bases. DeepXplore goes about DNN inference testing in an intelligent manner. It shows that finding inputs triggering differential behaviors while achieving high neuron cover...

Scalability, but at what COST

Image
This paper is by Frank McSherry, Michael Isard, Derek G. Murray and appeared in HotOS 2015. The authors are all listed as unaffiliated because this is around the time where Microsoft Research Silicon Valley lab was closed, where they used to work. Michael and Derek are at Google working on TensorFlow framework, but Frank McSherry is still at large and unaffiliated. Frank has a great blog, where you will learn more than you ever wanted to know about dataflow, Rust, differential privacy, and the art of influencing people and making friends.  COST, defined per system for a problem, is the configuration required before the system outperforms a competent single-threaded implementation. They show that many big data systems have surprisingly large COST, often hundreds of cores. Let's repeat this again: some single threaded implementations were found to be more than an order of magnitude faster than published results (at SOSP/OSDI!) for systems using hundreds of cores. The paper...

Paper Summary: Neurosurgeon, collaborative intelligence between the cloud and mobile edge

Image
This paper is by Yiping Kang, Johann Hauswald, Cao Gao, Austin Rovinski, Trevor Mudge, Jason Mars, and Lingjia Tang from University of Michigan, and appeared at ASPLOS 17. In Deep Learning (DL), you have a long, computation-intensive training phase where you micro-fiddle/fudge the model parameters until you get desired accuracy. Then you deploy this optimized model parameters (i.e., the Deep Neural Network [DNN])for inference with real-world inputs. The paper is about this inference/serving layer of DL. In the serving layer, the input goes through the DL with the tuned model parameters activating some subset of neurons at each layer and finally activating the correct neuron[s] at the output layer. This can still be a computation intensive process as the model has millions of parameters, and you apply matrix multiplication layer after layer. So this serving layer still has many juicy problems to work on. A very relevant problem is that executing inference at the mobile can be slow...

Paper summary: Making sense of Performance in Data Analytics Frameworks (NSDI 15)

Image
What constitutes the bottlenecks for big data processing frameworks? If CPU is a bottleneck, it is easy to fix: add more machines to the computation. Of course for any analytics job, there is some amount of coordination needed across machines. Otherwise, you are just mapping and transforming, but not reducing and aggregating information. And this is where the network and the disk as bottleneck comes into play. The reason you don't get linear speedup by adding more machines to an analytics job is the network and disk bottlenecks. And a lot of research and effort is focused on trying to optimize and alleviate the network and disk bottlenecks. OK this sounds easy, and it looks like we understand the bottlenecks in big data analytics. But this paper argues that there is a need to put more work into understanding the performance of big data analytics framework , and shows that at least for Spark on the benchmarks and workloads they tried (see Table 1), there are some counter intuitive...

Paper review: Prioritizing attention in fast data

Image
This paper appeared in CIDR17 and is authored by Peter Bailis, Edward Gan, Kexin Rong, and Sahaana Suri at Stanford InfoLab. Human attention is scarce, data is abundant. The paper argues, this is how we fight back: prioritize output: return fewer results prioritize iteration: perform feedback driven development and give useful details and allow user to tune the analysis pipeline   prioritize computation: aggressively filter and sample, tradeoff accuracy/completeness with performance where it has low impact, and use incremental data structures The slogan for the system is : MacroBase is a search engine for fast data. MacroBase employs a customizable combination of high-performance streaming analytics operators for feature extraction, classification, and explanation. MacroBase has a dataflow architecture (Storm, Spark Streaming, Heron). The paper argues it is better to focus on what dataflow operators to provide than to try to design from-scratch a new system (which won't...

Paper Review: Serverless computation with OpenLambda

Image
This paper provides a great accessible review and evaluation of the AWS Lambda architecture.  It is by Scott Hendrickson, Stephen Sturdevant, Tyler Harter, Venkateshwaran Venkataramani†, Andrea C. Arpaci-Dusseau, Remzi H. Arpaci-Dusseau, and it appeared at Hot Cloud 16 Virtual machines virtualized and shared the hardware so multiple VMs can colocate on the same machine. This allowed consolidation of machines, prevented the server sprawl problem, and reduced costs as well as improving manageability. The containers virtualized and shared the operating system, and avoided the overheads of VMs. They provided fast startup times for application servers. By "fast" we mean about 25 seconds of preparation time. In both VMs and containers, there is a "server" waiting for a client to serve to. Applications are defined as collection of servers and services. "Serverless" takes the virtualization a step ahead. They virtualize and share the runtime, and now the ...

Setting up a new Mac laptop

Image
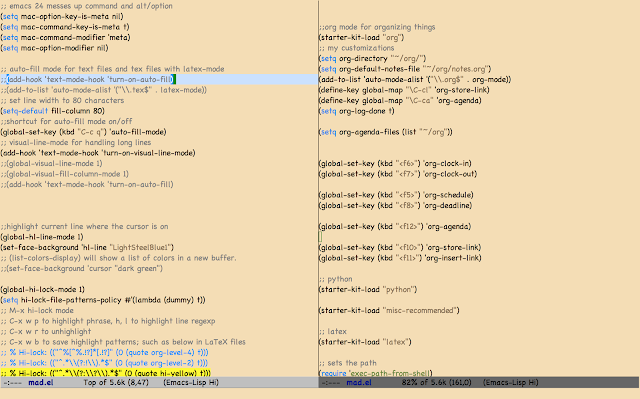
I install brew, and then install cask (using brew). Then I install mactex and emacs using cask. I install Dropbox, so my research directories get to sync. These days Opera is my browser of choice. I use f.lux and caffeine to get my monitor to behave. I can't live without some keyboard customizations. I open keyboard preferences, and get function keybindings to work without requiring the pressing of fn key. While there I map the CAPSLOCK to Control key. I use alt-left/right to traverse between desktops. My Emacs customization takes some time. I use the modularized emacs24-starter kit at http://eschulte.github.io/emacs24-starter-kit/ . It is great, it has good defaults, but it would be much better if it has better documentation and instructions. Since I install emacs using cask rather than from binary, I get to enjoy good package-manager support using ELPA. To see the available packages type M-x package-show-package-list. I install auctex, exec-path-from-shell, ipython,...

DARPA: Delivering Disruption

Image
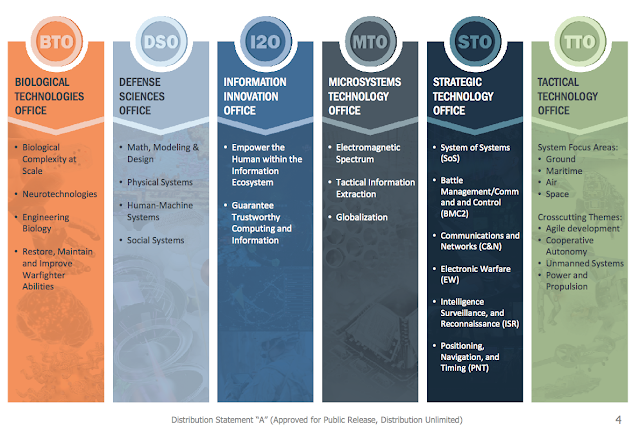
What does DARPA and Facebook have in common? Move fast and break things! A couple weeks ago Stefanie Tompkins, DARPA acting deputy director, visited University at Buffalo to give a talk and meet researchers. She talked about DARPA and funding opportunities at DARPA. I had the mental image of DARPA as a slow moving, hard to maneuver aircraft carrier , but her talk painted a very different picture, and partially changed my perception of DARPA. DARPA , then ARPA (Advanced Research Projects Agency), was created in 1958 as a response to Sputnik 1 . DARPA's mission is to prevent strategic surprise, avoid another Sputnik moment. And as you already know, the best way to predict future is to invent it. So DARPA is perpetually pushing the envelope to invent the next strategic surprise and disruptive technology itself. DARPA has a large number of successes under its belt. Internet has its roots in ARPANET.  GPS grew out of basic research on atomic clocks funded by DARPA. DARPA is also ...

Book Review: The Story of Your Life (by Ted Chiang)

The "Story of Your Life" is the science-fiction story which the Arrival film was based on. It was a very good read. Back in November, before the movie was released, I read it in less than 2 hours, in one breath. [Spoilers ahead.] The first couple pages of the book had some weird/mixed usage of the past future tense. Right at that first page, you get the idea that something is not right and this is going to be an interesting read. And as you keep reading, the story drops on you more clues, and you feel both smart and awed, when you first piece together that Gary was indeed the linguist's (Louise) first husband, and the daughter is not dead yet due to the climbing accident. Ted Chiang gives a lot of credit to the readers' intelligence. I liked that a lot. I also liked that I had to google and learn several things while reading the story. I googled to learn about "Fermat's principle", "teleology", "ideograms", and some related lin...

Paper summary: Federated Learning

Image
On Thursday, April 6, Google announced Federated Learning.   The announcement didn't make quite a splash, but I think this is potentially transformative. Instead of uploading all the data from the smartphones to the cloud for training the model in the datacenter, federated learning enables in-situ training at the smartphones themselves. The datacenter is still involved but it is involved for just aggregating the smartphone-updated local models in order to construct the new/improved global model. This is a win-win-win situation. As a smartphone user, your privacy is preserved since your data remains on your device, but you still get the benefits of machine learning on your smartphone. Google gets what it needs: it perpetually learns from cumulative user experience and improves its software/applications. Google collects insights without collecting data (and some of these insights may still be transferable to advertising income). Secondly, Google also outsources the training to the ...

1 million pageviews

Image
My blog has recently reached 1 million pageviews. This warrants for a short retrospection. I started the posting regularly on September 2010. I wanted to get into the cloud computing domain, so I needed to accumulate background on cloud computing work. I decided that as I read papers on cloud computing, I will post a summary to this blog. I thought if I could explain what I learned from the papers in my own words, I would internalize those lessons better. And if others read those summaries and benefit, that is an extra plus. "Writing is nature's way of telling you how sloppy your thinking is." In fact, I learned a lot writing those paper reviews. Writing the reviews gave me a deeper understanding of the work done, beyond what I could achieve by passively reading them. Putting them on web was also a nice choice, because I could refer my students to some of these summaries when needed. And it turned out that I referred to those summaries myself very frequently to jog ...

Bowling your way to the top

"Oh, this is very American!" I said, when I finally understood how Bowling scoring works. Bowling scoring is nonlinear In a bowling game, there are 10 rounds. There are 10 pins, and you get 2 shoots in each round to knock as many as you can. Even if you are novice, if you are eager and put effort in it, at each round you can knock down 6 pins. So that gives you a score of 6*10=60. If you knock down 7 pins at each round, you get a score of 70. 8 pins, you get a score of 80. 9 pins, you get a score of 90. Here is where things start to go nonlinear and you get accelerated returns. If you knock down all the 10 pins in your two shoots, this is called a spare. Your score for that round is not just 10, but the point you get from the next round is also added to it. So if you had a spare in round k, and got 7 in the next round k+1, you get 10+7 for round k, and 7 for round k+1, and in total of 17+7=24 points from these two rounds. If we were scoring this linearly, you wou...

Popular posts from this blog

The Man from the Future: Why Johnny Can't Stop Abstracting

The Safest Job from AI may be Writing

The Two Abstractions of System Design: Hide or Reduce

The Agentic Self: Parallels Between AI and Self-Improvement

In Search of a Compositional Theory of Self-Stabilization

Learning about distributed systems: where to start?

Building a Database on S3

Foundational distributed systems papers

What I'd do as a College Freshman in 2025

Cloudspecs: Cloud Hardware Evolution Through the Looking Glass