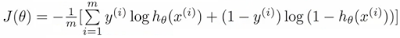Posts

Setting up a new Mac laptop
Image
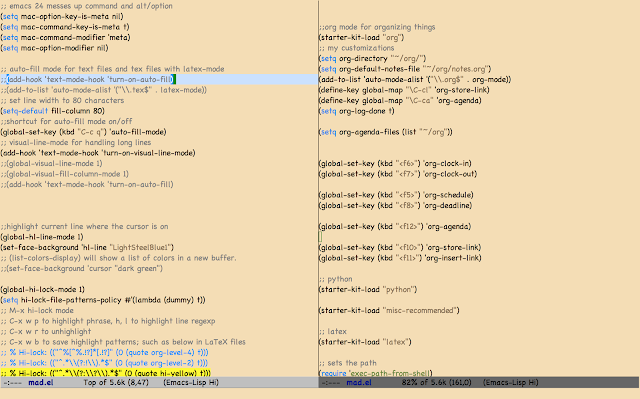
I install brew, and then install cask (using brew). Then I install mactex and emacs using cask. I install Dropbox, so my research directories get to sync. These days Opera is my browser of choice. I use f.lux and caffeine to get my monitor to behave. I can't live without some keyboard customizations. I open keyboard preferences, and get function keybindings to work without requiring the pressing of fn key. While there I map the CAPSLOCK to Control key. I use alt-left/right to traverse between desktops. My Emacs customization takes some time. I use the modularized emacs24-starter kit at http://eschulte.github.io/emacs24-starter-kit/ . It is great, it has good defaults, but it would be much better if it has better documentation and instructions. Since I install emacs using cask rather than from binary, I get to enjoy good package-manager support using ELPA. To see the available packages type M-x package-show-package-list. I install auctex, exec-path-from-shell, ipython,...
DARPA: Delivering Disruption

Image
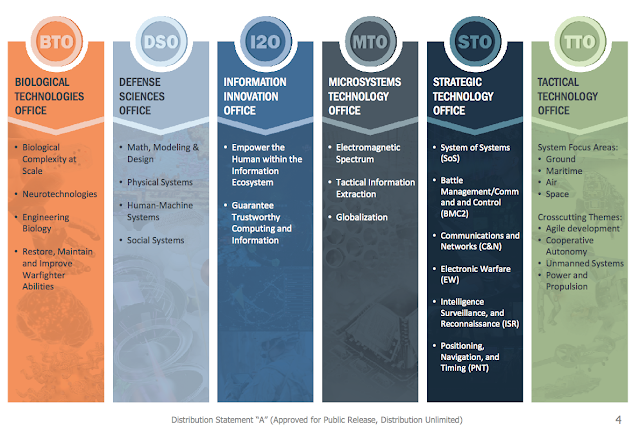
What does DARPA and Facebook have in common? Move fast and break things! A couple weeks ago Stefanie Tompkins, DARPA acting deputy director, visited University at Buffalo to give a talk and meet researchers. She talked about DARPA and funding opportunities at DARPA. I had the mental image of DARPA as a slow moving, hard to maneuver aircraft carrier , but her talk painted a very different picture, and partially changed my perception of DARPA. DARPA , then ARPA (Advanced Research Projects Agency), was created in 1958 as a response to Sputnik 1 . DARPA's mission is to prevent strategic surprise, avoid another Sputnik moment. And as you already know, the best way to predict future is to invent it. So DARPA is perpetually pushing the envelope to invent the next strategic surprise and disruptive technology itself. DARPA has a large number of successes under its belt. Internet has its roots in ARPANET.  GPS grew out of basic research on atomic clocks funded by DARPA. DARPA is also ...

Book Review: The Story of Your Life (by Ted Chiang)

The "Story of Your Life" is the science-fiction story which the Arrival film was based on. It was a very good read. Back in November, before the movie was released, I read it in less than 2 hours, in one breath. [Spoilers ahead.] The first couple pages of the book had some weird/mixed usage of the past future tense. Right at that first page, you get the idea that something is not right and this is going to be an interesting read. And as you keep reading, the story drops on you more clues, and you feel both smart and awed, when you first piece together that Gary was indeed the linguist's (Louise) first husband, and the daughter is not dead yet due to the climbing accident. Ted Chiang gives a lot of credit to the readers' intelligence. I liked that a lot. I also liked that I had to google and learn several things while reading the story. I googled to learn about "Fermat's principle", "teleology", "ideograms", and some related lin...

Paper summary: Federated Learning

Image
On Thursday, April 6, Google announced Federated Learning.   The announcement didn't make quite a splash, but I think this is potentially transformative. Instead of uploading all the data from the smartphones to the cloud for training the model in the datacenter, federated learning enables in-situ training at the smartphones themselves. The datacenter is still involved but it is involved for just aggregating the smartphone-updated local models in order to construct the new/improved global model. This is a win-win-win situation. As a smartphone user, your privacy is preserved since your data remains on your device, but you still get the benefits of machine learning on your smartphone. Google gets what it needs: it perpetually learns from cumulative user experience and improves its software/applications. Google collects insights without collecting data (and some of these insights may still be transferable to advertising income). Secondly, Google also outsources the training to the ...

1 million pageviews

Image
My blog has recently reached 1 million pageviews. This warrants for a short retrospection. I started the posting regularly on September 2010. I wanted to get into the cloud computing domain, so I needed to accumulate background on cloud computing work. I decided that as I read papers on cloud computing, I will post a summary to this blog. I thought if I could explain what I learned from the papers in my own words, I would internalize those lessons better. And if others read those summaries and benefit, that is an extra plus. "Writing is nature's way of telling you how sloppy your thinking is." In fact, I learned a lot writing those paper reviews. Writing the reviews gave me a deeper understanding of the work done, beyond what I could achieve by passively reading them. Putting them on web was also a nice choice, because I could refer my students to some of these summaries when needed. And it turned out that I referred to those summaries myself very frequently to jog ...

Bowling your way to the top

"Oh, this is very American!" I said, when I finally understood how Bowling scoring works. Bowling scoring is nonlinear In a bowling game, there are 10 rounds. There are 10 pins, and you get 2 shoots in each round to knock as many as you can. Even if you are novice, if you are eager and put effort in it, at each round you can knock down 6 pins. So that gives you a score of 6*10=60. If you knock down 7 pins at each round, you get a score of 70. 8 pins, you get a score of 80. 9 pins, you get a score of 90. Here is where things start to go nonlinear and you get accelerated returns. If you knock down all the 10 pins in your two shoots, this is called a spare. Your score for that round is not just 10, but the point you get from the next round is also added to it. So if you had a spare in round k, and got 7 in the next round k+1, you get 10+7 for round k, and 7 for round k+1, and in total of 17+7=24 points from these two rounds. If we were scoring this linearly, you wou...

Mesos: A platform for fine-grained resource sharing in the data center

Image
This paper appeared in NSDI 11 and introduced the Mesos job management and scheduling platform which proved to be very influential in the big data processing ecosystem. Mesos has seen a large following because it is simple and minimalist. This reminds me of the  "worse is better" approach to system design. This is an important point and I will ruminate about this after I explain you the Mesos platform. The problem  We need to make multiple frameworks coexist and share the computing resources in a cluster. Yes, we have submachine scheduling abstractions: first the virtual machines and then containers. But we still need a coordinator/arbiter to manage/schedule jobs submitted from these frameworks  to make sure that we don't underutilize or overload/overtax the resources in the cluster. Offer-based scheduling Earlier, I have talked about Borg which addressed this cluster management problem. While Borg (and later Kubernetes) takes a request-based scheduling approac...

Large-scale cluster management at Google with Borg

Image
This paper from Google appeared on Eurosys'15 . The paper presents Borg, the cluster management system Google used since 2005. The paper includes a section at the end about the good and bad lessons learned from using Borg, and how these led to the development of Kubernetes container-management system which empowers the Google Cloud Platform and App Engine. Borg architecture This is the Borg. Resistance is futile. A median Borg cell is 10K machines. And all those machines in a cell are served by a logically centralized control: the Borgmaster. Where is the bottleneck in the centralized Borg architecture? The paper says it is still unclear whether this architecture would hit a practical scalability limit. Anytime Borg was given a scalability target, they managed to achieve it by applying basic techniques: caching, loose-synchronization, and aggregation. What helped the most for achieving scalability was decoupling the scheduler component from the Borgmaster. The scheduler...

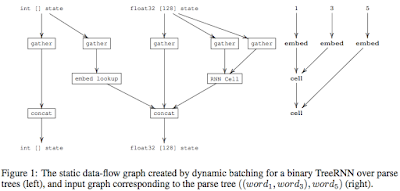
Deep Learning With Dynamic Computation Graphs (ICLR 2017)

Image
This is a paper by Google that is under submission to ICLR 2017. Here is the OpenReview link for the paper. The paper pdf as well as paper reviews are openly available there. What a concept! This paper was of interest to me because I wanted to learn about dynamic computation graphs. Unfortunately almost all machine learning/deep learning (ML/DL) frameworks operate on static computation graphs and can't handle dynamic computation graphs. (Dynet and Chainer are exceptions). Using dynamic computation graphs allows dealing with recurrent neural networks (RNNs) better, among other use cases. ( Here is a great article about RNNs and LSTMs . Another good writeup on RNNs is here .) TensorFlow already supports RNNs , but by adding padding to ensure that all input data are of the same size, i.e., the maximum size in the dataset/domain. Even then this support is good only for linear RNNs not good for treeRNNs which is suitable for more advanced natural language processing. This was a ve...

My first impressions after a week of using TensorFlow

Image
Last week I went through the TensorFlow (TF) Tutorials here . I found that I hadn't understood some important points about TensorFlow execution, when I read the TensorFlow paper. I am noting them here fresh to capture my experience as a beginner. (As one gathers more experience with a platform, the baffling introductory concepts starts to occur obvious and trivial.) The biggest realization I had was to see a dichotomy in TensorFlow among two phases. The first phase defines a computation graph (e.g., a neural network to be trained and the operations for doing so). The second phase executes the computation/dataflow graph defined in Phase1 on a set of available devices. This deferred execution model enables optimizations in the execution phase by using global information about the computation graph: graph rewriting can be done to remove redundancies, better scheduling decisions can be made, etc. Another big benefit is in enabling flexibility and ability to explore/experiment in the ...

Google DistBelief paper: Large Scale Distributed Deep Networks

Image
This paper introduced the DistBelief deep neural network architecture. The paper is from NIPS 2012. If you consider the pace of progress in deep learning, that is old and it shows. DistBelief doesn't support distributed GPU training which most modern deep networks (including TensorFlow) employ. The scalability and performance of DistBelief has been long surpassed. On the other hand, the paper is a must read if you are interested in distributed deep network platforms. This is the paper that applied the distributed parameter-server idea to Deep Learning. The parameter-server idea is still going strong as it is suitable to serve the convergent iteration nature of machine learning and deep learning tasks. The DistBelief architecture has been used by the  Microsoft Adam project , Baidu Deep Image , Apache Hama , and Petuum's Bosen . Google, though, has since switched from the DistBelief parameter-server to TensorFlow's hybrid dataflow architecture, citing the difficulty of cus...

Learning Machine Learning: Deep Neural Networks

Image
This post is part of the ML/DL learning series. Earlier in the series, we covered these: + Learning Machine Learning: A beginner's journey  + Linear Regression + Logistic Regression + Multinomial Logistic Regression In this part, we are going to add hidden layers to our neural network, learn how backpropagation works for gradient descent in a deep NN, and finally talk about regularization techniques for avoiding overfitting. For this post also, I follow the course notes from the Udacity Deep Learning Class by Vincent Vanhoucke at Google. Go, take the course. It is a great course to learn about deep learning and TensorFlow. Linear models are limited  We constructed a single layer NN for multinomial regression in our last post. How many parameters did that NN have? For an input vector X of size N, and K output classes, you have (N+1)*K parameters to use. N*K is the size of W, and K is the size of b. You will need to use many more parameters in practice. Deep learni...

Learning Machine Learning: Multinomial Logistic Classification

Image
In the previous post, we got started on classification. Classification is the task of taking an input and giving it a label that says, this is an "A". In the previous post, we covered logistic regression, which made the decision for a single label "A". In this post, we will generalize that to multinomial logistic classification where your job is to figure out which of the K classes a given input belongs to. For this post I follow the course notes from the Udacity Deep Learning Class by Vincent Vanhoucke at Google . I really liked his presentation of the course: very practical and to the point. This must have required a lot of preparation. Going through the video transcript file, I can see that the material has been prepared meticulously to be clear and concise. I strongly recommend the course. The course uses TensorFlow to teach you about Deep Neural Networks in a hands-on manner, and follows the MNIST letter recognition example in the first three lessons. Don...

Popular posts from this blog

The Safest Job from AI may be Writing

The Two Abstractions of System Design: Hide or Reduce

The Agentic Self: Parallels Between AI and Self-Improvement

In Search of a Compositional Theory of Self-Stabilization

Learning about distributed systems: where to start?

Hints for Distributed Systems Design

Foundational distributed systems papers

Building a Database on S3

Cloudspecs: Cloud Hardware Evolution Through the Looking Glass

Specula: Scaling formal specifications for autonomous model checking of system code