Posts

Modular Composition of Coordination Services
Image
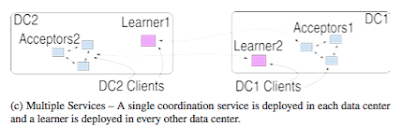
This paper appeared in Usenix ATC'16 last week.  The paper considers the problem of scaling ZooKeeper to WAN deployments. ( Check this earlier post for a brief review of ZooKeeper. ) The paper suggests a client-side only modification to ZooKeeper, and calls the resultant system ZooNet. ZooNet consists of a federation of ZooKeeper cluster at each datacenter/region. ZooNet assumes the workload is highly-partitionable, so  the data is partitioned among the ZooKeeper clusters, each accompanied by learners in the remote datacenter/regions. Each ZooKeeper cluster processes only updates for its own data partition and if applications in different regions need to access unrelated items they can also do so independently and in parallel at their own site. However, the problem with such a deployment is that it does not preserve ZooKeeper's sequential execution semantics. Consider the example in Figure 1. (It is not clear to me why the so-called "loosely-coupled" application...
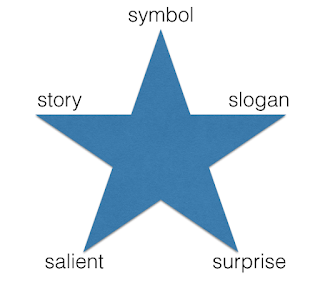
How to package your ideas using the Winston star

Image
I came across this advice serendipitously by reading a random Hacker News comment. The advice shows up towards the last 10 minutes of an Artificial Intelligence lecture by Patrick Winston. Winston, a prominent professor at MIT , tells his class that he will disclose them important advice that may make or break their careers. It is about how to pack and present ideas. His advice is simple. Follow this 5-tip star to pack your ideas better. All the tips start with "S": Symbol: use a symbol to make your idea visual and memorable Slogan: find a catchy slogan for your idea Surprise: highlight the unconventional/counterintuitive/interesting part of your idea Salient: focus on the essential part of your idea, remember: less is more, fewer ideas is better Story: pack your idea with a story, human brains are hardwired for stories Here let me try to apply the  Winston's Star method on itself, to make this more concrete. Symbol: star is the symbol of the Winston...

Nobody wants to read your shit

Earlier I wrote about how much I liked the "The War of Art" by Steven Pressfield. This newly released book by Pressfield takes on where "The War of Art" has left. While the former focused on the psychological aspects of the writing process, this book focuses on the structural/mechanical aspects of writing. The book was freely distributed as pdf and ebook for a limited time for promotion purposes. (It looks like the promotion ended.)  I read it in one sitting and found it interesting. This book can benefit anyone who needs to communicate in writing. (Of course, if you are a novice writer, start with the Elements of Style .) The book gives a very interesting account of what Steven learned from a 50+ years career performing all forms of writing, including ad writing, Hollywood script-writing, novels, and nonfiction. The first chapter lays down the most important lesson Steven has learned: "Nobody wants to read your shit", and the rest of the book talks abou...

Progress by impossibility proofs

I recently listened to this TED talk by Google X director Astro Teller. The talk is about the Google X moonshot projects, and the process they use for managing them. Google X moonshot projects aim to address big, important, and challenging problems.  Teller tells (yay, pun!) that the process they manage a moonshot project is basically to try to find ways to kill the project. The team first tries to identify the bottleneck at a project by focusing on the most important/critical/risky part of the project. Then they try to either solve that hardest part or show that it is unsolvable (in a feasible manner) and kill the project. Teller claims that, at Google X, they actually incentivize people to kill the project by awarding bonuses, and celebrate when a project gets proved impossible and killed. And if a project still survives, that is a successful moonshot project that has potential for transformative change. Although, this approach looks counter intuitive at first, it is a...

TensorFlow: A system for large-scale machine learning

Image
This paper has been uploaded to arxiv.org on May 27 2016, so it is the most recent description of Google TensorFlow. ( Five months ago, I had commented on an earlier TensorFlow whitepaper , if you want to check that first.) Below I summarize the main points of this paper by using several sentences/paragraphs from the paper with some paraphrasing. I end the post with my wild speculations about TensorFlow. (This speculation thing is getting strangely addictive for me.) TensorFlow is built leveraging Google's experience with their first generation distributed machine learning system, DistBelief. The core idea of this paper is that TensorFlow's dataflow representation subsumes existing work on parameter server systems (including DistBelief), and offers a uniform programming model that allows users to harness large-scale heterogeneous systems, both for production tasks and for experimenting with new approaches. TensorFlow versus Parameter Server systems DistBelief was based o...

Useful podcasts

I love listening to podcasts while commuting. I find that I learn a lot by listening to my selected list of podcasts, than just listening to the radio. I am blissfully ignorant about elections, US politics, and celebrity gossip. Here are the podcasts I have been listening to. I will appreciate if you can let me know of your recommendations. Who said podcasting is dead? (Here is one tip you may find useful. I listen to my podcasts at 1.5x speed. It is actually a more comfortable and natural way to listen to stuff than 1x. 1x is too slow, your brain starts losing the stream of conversation due to the slow pace, and starts wondering around. Give 1.5x a try.) Dan Carlin's Hardcore History Who knew history could be this interesting and captivating. Dan Carlin, a seasoned radio host and American political commentator, found his true calling in this podcasts series about history. The episodes are long, 4 hour episodes. But they are so exciting and captivating. I found myself depre...

Paper review. GraphLab: A new Framework for Parallel Machine Learning

Image
This GraphLab paper is from 2010. It is written elegantly and it does a good job of explaining the GraphLab abstraction and foundations. A later VLDB 2012 paper presents how to extend this basic GraphLab abstraction to a distributed GraphLab implementation. It seems like GraphLab has since took off big time. There are workshops and conferences about GraphLab. And GraphLab is now developed by the company Dato (formerly GraphLab inc.). Dato Inc. raised 6.75M$ from Madrona and New Enterprise Associates in A round, and 18.5M$ in B round from Vulcan Capital and Opus Capital, as well as Madrona and New Enterprise Associates. Introduction The motivation for GraphLab was to hit the sweetspot in development of machine learning solutions. "(Then in 2010) Existing high-level parallel abstractions like MapReduce are insufficiently expressive, while low-level tools like MPI and Pthreads leave machine learning (ML) experts repeatedly solving the same design challenges." GraphLab a...

Book review: The War Of Art by Steven Pressfield

I read this book recently and liked it a lot. The book is written by Steven Pressfield. He is also the writer of "The Legend of Bagger Vance" and "Gates of Fire" (arguably the best book about Spartans, and is being used as recommended reading in Army academies). Pressfield definitely knows and respects his craft. This book is a call for all people, and creative people and writers in particular, to wake up and realize their calling. The book says: "Most of us have two lives. The life we live, and the unlived life within us." Yeah... About that... I know "self-help" books, and books that use "new-agey" language rub many people the wrong way. I am a pragmatic about that. The way I see it, if I can learn some good paradigms, tips, strategy to become more productive, effective, I can look past some of the turn-offs. The book is organized in 3 parts. The first part talks about resistance, the enemy of creating anything meaningful and wort...

Consensus in the Cloud: Paxos Systems Demystified

Image
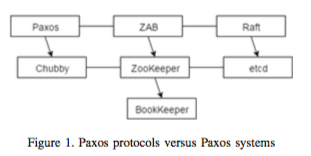
This our most recent paper, still under submission. It is available as a technical report here. We felt we had to write this paper because we have seen misuses/abuses of Paxos-based coordination services. Glad this is off our chests. Here is the short pitch for the paper. I hope you like it and find it helpful. Coordination and consensus play an important role in datacenter and cloud computing. Examples are leader election, group membership, cluster management, service discovery, resource/access management, and consistent replication of the master nodes in services. Paxos protocols and systems provide a fault-tolerant solution to the distributed consensus problem and have attracted significant attention but they also  generated substantial confusion. Zab, Multi-Paxos, Raft are examples of Paxos protocols.  ZooKeeper, Chubby, etcd are examples of Paxos systems. Paxos systems and Paxos protocols reside in different planes, but even that doesn't prevent these two concepts...

Paper Review. Petuum: A new platform for distributed machine learning on big data

Image
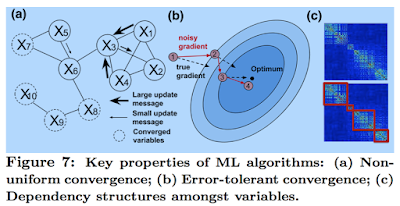
First there was big data. Industry saw that big data was good. Industry made big data storage systems, NoSQL datastores, to store and access the big data. Industry saw they were good. Industry made big data processing systems, Map Reduce, Spark, etc., to analyze and extract information and insights (CRM, business logistics, etc.) from big data. Industry saw they were good and popular, so machine learning libraries are added to these big data processing systems to provide support for machine learning algorithms and techniques. And here is where this paper makes a case for a redesign for machine learning systems. The big data processing systems produced by the industry are general analytic systems, and are not specifically designed for machine learning from the start. Those are data analytics frameworks first, with some machine learning libraries as add on to tackle machine learning tasks. This paper considers the problem of a clean slate system design for a big data machine learning s...

Paper review: Building Consistent Transactions with Inconsistent Replication (SOSP'15)

Image
This paper investigates an interesting and promising research problem: how can we implement distributed transactions more efficiently by performing a cross-layer design of the transaction protocal/layer with the underlying distributed storage protocol/layer? This idea is motivated by the observation that there is wasted/duplicated work done both at the transaction layer and at the storage layer. The transaction layer already provides ordering (i.e., linearizability), and, if you look at the distributed storage layer, it also provides strongly consistent replication which orders/linearizes updates often with Paxos. The paper argues that this is overlapping functionality, and leads to higher latency and lower throughput. Ok, at this point, we have to take a step back and realize that we cannot avoid all coordination between the two layers. The distributed storage layer needs to be consistent with the order of updates at the transaction layer, because it serves reads and you like it to...

Paper review: Measuring and Understanding Consistency at Facebook

Image
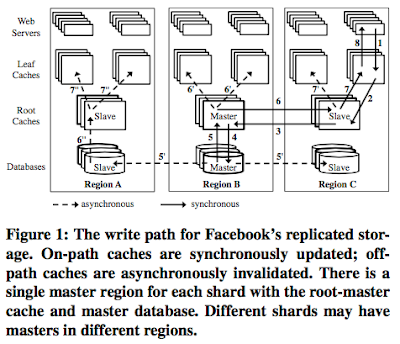
I have reviewed many Facebook papers in this blog before (see the links at the bottom for full list). Facebook papers are simple (in the good sense of the word) and interesting due to the huge scale of operation at Facebook. They are testaments of high scalability in practice. This one here is no different. This paper investigates the consistency of the Facebook TAO system. The TAO system is a replicated storage system for Facebook's social graph of billion vertices. In theory, TAO provides only eventual consistency. The interesting result in this paper is this: In practice, Facebook's TAO system is highly consistent, with only 5 inconsistency violations out of a million read requests! Facebook's TAO system TAO is basically 2-level memcached architecture backed by a database, as first discussed in NSDI'13 paper.  TAO architecture is given in Figure 1. As a prerequisite to TAO consistency discussion in the next section, it will be enough to review how TAO serves re...

Paper review: Implementing Linearizability at Large Scale and Low Latency (SOSP'15)

Image
Motivation for the paper Remember the 2-phase commit problem?  The 2-phase commit blocks when the initiator crashes. Or, after a server crash the client/initiator may not be able to determine whether the transaction is completed. And transaction blocks. Because if we retry we may end up giving inconsistent result or redoing the transaction which messes up linearizability. You need to have 3-phase commit to fix this. The new-leader/recovery-agent comes and tries to recommit things. Unfortunately, 3-phase commit solutions are complicated, there are a lot of corner cases. Lamport and Gray recommended that the Paxos consensus box can be used to remember the initiator's abort commit decision to achieve consistency, or more precisely they recommended the Paxos box remembers each participants decision  for the sake of shaving off a message in critical latency path. What this paper recommends is an alternative approach. Don't use Paxos box to remember the decision, instead use ...

Popular posts from this blog

The Safest Job from AI may be Writing

The Two Abstractions of System Design: Hide or Reduce

The Agentic Self: Parallels Between AI and Self-Improvement

In Search of a Compositional Theory of Self-Stabilization

Learning about distributed systems: where to start?

Hints for Distributed Systems Design

Foundational distributed systems papers

Building a Database on S3

Cloudspecs: Cloud Hardware Evolution Through the Looking Glass

Specula: Scaling formal specifications for autonomous model checking of system code