Posts

Centrifuge: Integrated Lease Management and Partitioning for Cloud Services

Image
For performance reasons many large-scale sites (LinkedIn, Digg, Facebook, etc.) employ a pool of backend servers that operate purely on in-memory state. The frontend servers that forward the requests to the backend servers then should be very carefully implemented to ensure that they forward the requests to the correct backends. The frontend should ensure that the selected backend has the requested object in its memory and also possesses the lease to update the object. Unfortunately, things may change quickly at the backend; backend servers may fail, new ones may join, backend servers may start to cache different objects due to load-balancing requirements, and leases may exchange hands. All of these make the task of programming the frontend very challenging and frustrating. This work (from NSDI'10) proposes Centrifuge, a datacenter lease manager that addresses this problem. The Centrifuge system has been deployed as part of Microsoft live mesh service, a large scale commercial clo...
Smoke and Mirrors: Reflecting Files at a Geographically Remote Location Without Loss of Performance

Image
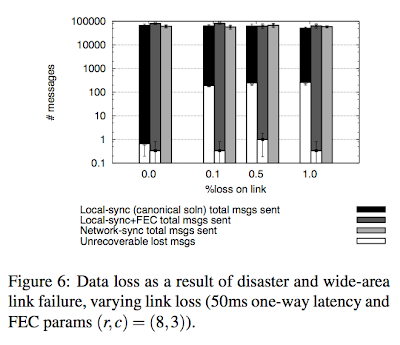
This paper from FAST'09 introduces smoke and mirrors filesystem (SMFS) which mirrors files at a geographically remote datacenter with negligible impact on performance. It turns out remote mirroring is a major problem for banking systems which keep off-site mirrors (employing dedicated high-speed 10-40Gbits optical links) to survive disasters. This paper is about disaster tolerance, not your everyday fault-tolerance. The fault model includes that the primary site may get destroyed, and some sporadic packet losses upto 1% may occur simultaneously as well, yet still no data should be lost. (Data is said to be lost if the client is acknowledged for the update but the corresponding update/data no longer exists in the system.) The primary site being destroyed may be a bit over-dramatization. An equivalent way to state the fault model would be that the paper just rules out a post~hoc correction (replay or manual correction). Here is how manual correction would work: if power outage occur...

Consistency analysis in Bloom: a CALM and collected approach

This work from CIDR11 aims to provide theoretical foundations for correctness under eventual consistency, and identifies "order independence" (independence of program execution from temporal nondeterminism) as a sufficient condition for eventual consistency. CALM (consistency and logical monotonicity) principle states that monotonic programs guarantee order independence, and hence, eventual consistency. A monotonic program is one where any true statement remains to be true as new axioms arrive. In contrast, in a non-monotonic program, new input can cause the earlier output to be revoked. A monotonic program guarantees eventual consistency, whereas non-monotonicity requires the use of coordination logic. To simplify the task of identifying monotonic and nonmonotonic program segments, this work proposes using program analysis in a declarative language, Bloom. In Bloom, monotonicity of a program is examined via simple syntactic checks. Selection, join, and projection operators ...

Life beyond Distributed Transactions: an Apostate's Opinion

Image
Pat Helland is one of the veterans of the database community. He worked on the Tandem Computers with Jim Gray. His tribute to Jim Gray , which gives a lot of insights into Jim Gray as a researcher, is worth reading again and again. This 2007 position paper from Pat Helland is about extreme scalability in cloud systems, and by its nature anti-transactional. Since Pat has been a strong advocate for transactions and global serializability for most of his career, the title is aptly named as an apostate's opinion. This paper is very relevant to the NoSQL movement . Pat introduces "entity and activities" abstractions as building primitives for extreme scalability cloud systems. He also talks about at length about the need to craft a good workflow/business-logic on top of these primitives. Entity and activities abstractions Entities are collections of named (keyed) data which may be atomically updated within the entity but never atomically updated across entities. An entity liv...

Tempest and Deutronomy reviews

I am 3 weeks behind in writing summaries for the papers we discuss in my seminar. In order to have some chance of catching up, I am skipping the summaries for Tempest and Deutronomy papers, and refer to student summaries for these two. Tempest: Soft state replication in the service tier (DSN'08) Deuteronomy: Transaction Support for Cloud Data (CIDR'11)

Megastore: Providing scalable, highly available storage for interactive services

Image
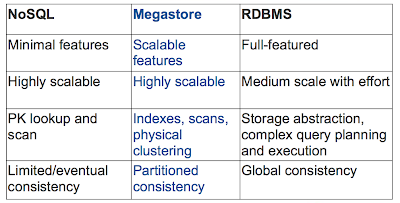
Google's Megastore is the structured data store supporting the Google Application Engine . Megastore handles more than 3 billion write and 20 billion read transactions daily and stores a petabyte of primary data across many global datacenters. Megastore tries to provide the convenience of using traditional RDBMS with the scalability of NOSQL: It is a scalable transactional indexed record manager (built on top of BigTable), providing full ACID semantics within partitions but lower consistency guarantees across partitions (aka, entity groups in Figure 1). To achieve these strict consistency requirements, Megastore employs a Paxos-based algorithm for synchronous replication across geographically distributed datacenters. I have some problems with Megastore, but I save them to the end of the review to explain Megastore first. Paxos Megastore uses Paxos , a proven, optimal, fault-tolerant consensus algorithm with no requirement for a distinguished master. (Paxos is hard to cover i...

Flexible, Wide-Area Storage for Distributed Systems with WheelFS

One of my students, Serafettin Tasci , wrote a good review of this paper, so I will save time by using his review below, instead of writing a review myself. In this paper the authors propose a storage system for wide-area distributed systems called WheelFS. The main contribution of WheelFS is its ability of adaptation to different types of applications with different consistency, replica placement or failure handling requirements. This ability is obtained via semantic cues that can be easily expressed in path names. For example to force the primary site of a folder john to be X, we can specify the cue “home/users/.Site=X/john”. This representation enables preserving of POSIX semantics and minor change in application software to use the cues. In WheelFS, there are 4 groups of semantic cues. Placement cues are used to arrange the location of primaries and replicas of a file or folder. Durability cues specify the number and usage of replicas. Consistency cues maintain a tradeoff between ...

Ceph: A Scalable, High-Performance Distributed File System

Image
Traditional client/server filesystems (NFS, AFS) have suffered from scalability problems due to their inherent centralization. In order to improve performance, modern filesystems have taken more decentralized approaches. These systems replaced dumb disks with intelligent object storage devices (OSDs)--which include CPU, NIC and cache-- and delegated low-level block allocation decisions to these OSDs. In these systems, clients typically interact with a metadata server (MDS) to perform metadata operations (open, rename), while communicating directly with OSDs to perform file I/O (reads and writes). This separation of roles improve overall scalability significantly. Yet, these systems still face scalability limitations due to little or no distribution of the metadata workload. Ceph is a distributed file system designed to address this issue. Ceph decouples data and metadata operations completely by eliminating file allocation tables and replacing them with generating functions (called CR...

Sinfonia: A New Paradigm for Building Scalable Distributed Systems

Image
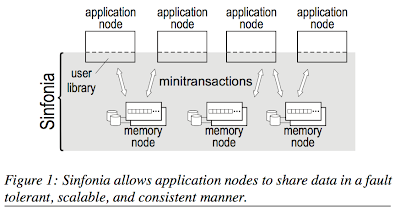
Sinfonia is an in-memory scalable service/infrastructure that aims to simplify the task of building scalable distributed systems. Sinfonia provides a lightweight "minitransaction" primitive that enables applications to atomically access and conditionally modify data at its multiple memory nodes. As the data model, Sinfonia provides a raw linear address space which is accessed directly by client libraries. Minitransactions In traditional transactions, a coordinator executes a transaction by asking participants to perform one or more participant-actions (such as retrieving or modifying data items), and at the end of the transaction, the coordinator decides and executes a two-phase commit. In the first phase, the coordinator asks all participants if they are ready to commit. If they all vote yes, in the second phase the coordinator tells them to commit; otherwise the coordinator tells them to abort. Sinfonia introduces the concept of minitransactions, by making the observation...

PetaShare: A reliable, efficient and transparent distributed storage management system

Image
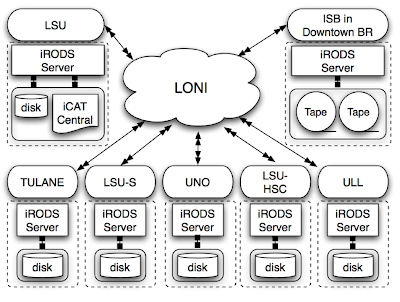
This paper by my colleague Tevfik Kosar (to appear soon) presents the design and implementation of a reliable and efficient distributed data storage system, PetaShare, which manages 450 Terabytes of disk storage and spans 7 campuses across the state of Louisiana. There are two main components in a distributed data management architecture: a data server which coordinates physical access (i.e. writing/reading data sets to/from disks) to the storage resources, and a metadata server which provides the global name space and metadata of the files. Metadata management is a challenging problem in widely distributed large-scale storage systems, and is the focus of this paper. Petashare architecture The back-end of PetaShare is based on iRODS . All system I/O calls made by an application are mapped to the relevant iRODS I/O calls. iRODS stores all the system information, as well as user-defined rules in centralized database, which is called iCAT. iCAT contains the information of the distributed...

Volley: Automated Data Placement for Geo-Distributed Cloud Services

Image
Datacenters today are distributed across the globe, yet they need to share data with other datacenters as well as their clients. This paper from Microsoft Research presents a heuristic strategy for data placement to these geo-distributed datacenters. While there has been previous work on data placement in LANs and WSNs, Volley is the first heuristic for data placement strategies for WANs. A simple heuristic is to place each data to the datacenter closest to the client of that data. But things are not that simple, there are several additional constraints to be considered, including business constraints, WAN bandwidth costs, datacenter capacity limits, data interdependencies, user-perceived latency, etc. For example, it makes more sense to collocate data that are tightly-coupled/interdependent, such as two friends in Facebook that update each other walls. As another example, the frequency of the clients accessing the data needs to be taken in to account as well. As live mesh and live m...

PNUTS: Yahoo!'s hosted data serving platform

Given that web users are scattered across the globe, it is critical to have data replicas on multiple continents for low-latency access and high-availability. Supporting general transactions is typically unnecessary, since web applications tend to manipulate only one record at a time. Moreover, supporting general transactions (with serializability) over a globally-replicated distributed system is expensive and impractical. On the other hand, it is still useful to have a stronger consistency guarantee than the very weak "eventual consistency" . It is often acceptable to read slightly stale data but having replicas use the same order of updates is important because out of order updates may expose undesirable (outside the invariant, unsafe) state at some replicas. The most important contribution of the PNUTS paper is an asynchronous replication architecture that achieves serializability of writes to each record. This feat is achieved by using record-level masters. Record-leve...

Chain replication for supporting high throughput and availability

Image
Chain replication (2004) is a replication protocol to support large-scale storage services (mostly key-value stores) for achieving high throughput and availability while providing strong consistency guarantees. Chain replication is essentially a more efficient retake of primary-backup replication. The below figure explains it all. I really love the way the protocol is presented as a stepwise-refinement starting from the high-level specificaiton of a storage system. This exposition provides a simple way of justifying the correctness of the protocol (especially for fault-tolerance actions for handling failures of servers), and also is convenient for pointing out to other alternative implementations. Chain replication protocol There are two types of requests, a query request (read) and an update request (write). The reply for every request is generated and sent by the tail. Each query request is directed to the tail of the chain and processed there atomically using the replica of obj...

Pond: The Oceanstore prototype

Image
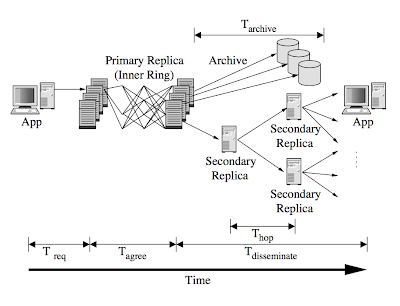
This paper details the implementation of Pond, a distributed p2p filesystem for object-storage. Pond is a prototype implementation of Oceanstore, which was described here. Oceanstore is especially notable by its elegant solution to localization of objects in a P2P environment (employing Tapestry and using attenuated Bloom filters as hints for efficient search). Architecture The system architecture is two tiered. The first tier consists of well connected hosts which serialize updates (running Byzantine agreement) and archive results. The second tier provides extra storage/cache resources to the system. Replication and caching Pond uses "erasure codes" idea for efficient and robust storage. Given storage is virtually unlimited today, they could as well have used full-replication and saved a lot of headache to themselves. The erasure coding leads to problems when reading. Several machines need to be contacted to reconstruct the block. What Pond does is, after a block is const...

SEDA: An architecture for well-conditioned scalable internet services

Image
A service is well-conditioned if it behaves like a simple pipeline: as the offered load increases, the delivered throughput increases proportionally until the pipeline is full and the throughput saturates; additional load should not degrade throughput. Moreover, after saturation, the response time should not increase faster than linearly with the number of clients. Hence, the key property of a well-conditioned service is graceful degradation: as offered load exceeds capacity, the service maintains high throughput with a linear response-time penalty. Unfortunately, that is not the typical web experience; as load increases beyond saturation point throughput decreases and response time increases dramatically, creating the impression that the service has ground to a halt. SEDA enables services to be well-conditioned to load, preventing resources from being overcommitted when demand exceeds service capacity. In other words, SEDA makes it easy to do load-shedding and to sacrifice the Q in t...

Popular posts from this blog

The Safest Job from AI may be Writing

The Two Abstractions of System Design: Hide or Reduce

The Agentic Self: Parallels Between AI and Self-Improvement

In Search of a Compositional Theory of Self-Stabilization

Learning about distributed systems: where to start?

Hints for Distributed Systems Design

Foundational distributed systems papers

Building a Database on S3

Cloudspecs: Cloud Hardware Evolution Through the Looking Glass

Specula: Scaling formal specifications for autonomous model checking of system code